AI Servers
AI Servers for Training, Inference and HPC
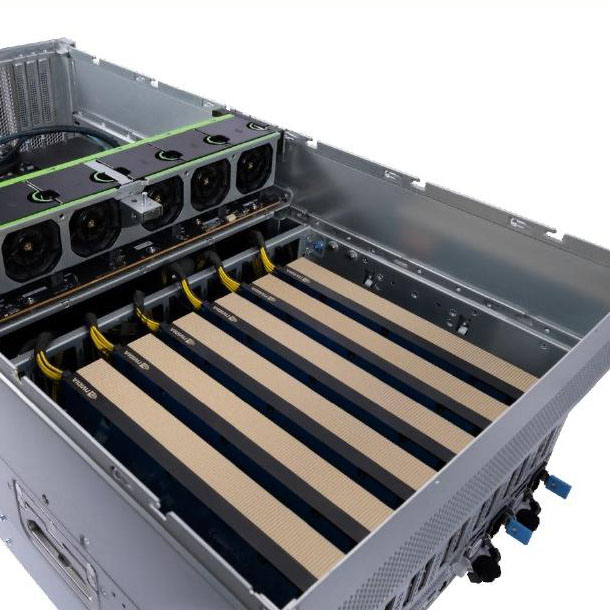
Accelerate large-scale AI innovation with high-density AI servers built for the most demanding GPU workloads. BEIJING YINTAI provides configurable AI server platforms designed for large language model (LLM) training, model fine-tuning, real-time inference, computer vision, and scientific computing.
Modern AI infrastructure requires a full-stack balance of accelerated compute, high-bandwidth networking, scalable storage, power delivery, and thermal design. BEIJING YINTAI coordinates GPU-dense server projects through qualified manufacturing partners. Available options can include flexible PCIe accelerator configurations and OAM/HGX-oriented training nodes, subject to the selected platform, accelerator availability, software stack, and final bill of materials.
Product Overview
| Feature | Description |
|---|---|
| Form Factors | Selected 4U, 6U, and 10U rackmount platforms, with other chassis options evaluated by project. |
| GPU Density | Qualified configurations can support 4 or 8 accelerators per node, depending on platform, topology, power, and cooling. |
| Accelerator Options | Validated reference configurations across premium, balanced, and cost-optimized tiers. |
| Topology Flexibility | Workload-driven GPU topology including Direct, Balance, Cascade, and Common configurations. |
| Advanced Networking | High-speed InfiniBand and RoCE Ethernet options for qualified cluster configurations. |
| Thermal Engineering | Airflow, power delivery, and thermal plans validated against the selected component set and workload. |
Core Technology Modules
Workload-Driven GPU Topology Design
Deploying AI infrastructure is a thermal and topological engineering challenge. We support various PCIe switch topologies to match data transfer requirements, designed to maintain continuous data flow to GPUs.
• Direct Topology: well-suited for workloads requiring minimal latency and direct CPU-to-GPU communication.
• Balance Topology: Distributes workloads evenly across GPUs, suitable for general-purpose AI tasks.
• Cascade Topology: Optimized for specific AI models that benefit from hierarchical data flow.
• Common Topology: A versatile configuration that supports a wide range of standard AI and HPC applications.
High-Performance Accelerator Configurations
We coordinate reference configurations for different workload and budget requirements. The final system requires compatibility, stability, power, and thermal validation against the approved component set and software environment.
• Premium Tier: Designed for large-scale parameter LLM training and complex HPC simulations, featuring flagship data-center GPUs and high-speed interconnects.
• Balanced Tier: well-suited for enterprise fine-tuning, private AI deployments, and demanding inference workloads, offering a strong balance of performance and cost.
• Cost-Optimized Tier: For selected inference and research projects, an engineered blower-cooled RTX 5090 accelerator option may be evaluated as part of a qualified deployment.
Advanced Thermal and Power Engineering
High-density AI servers generate significant heat and require robust power delivery systems. Our platforms are engineered to handle the thermal and electrical demands of modern GPUs.
• Airflow Planning: Chassis airflow channels and fan selection are matched to the approved component set.
• Power Delivery: Redundant power-supply options and power budgets are selected according to platform and accelerator requirements.
• Thermal Validation: The agreed test plan can include thermal and workload validation before deployment.
Cluster-Scale Networking and Storage
AI workloads require high-bandwidth, low-latency networking and scalable storage to keep GPUs fed with data.
• High-Speed Interconnects: Designed to accommodate multiple 200Gb/s or 400Gb/s InfiniBand or RoCE Ethernet adapters.
• Scalable Storage: Support for high-performance NVMe storage to minimize data loading times.
Reference Configuration Tiers
| Tier | Target Workloads | Key Characteristics |
|---|---|---|
| Premium | LLM Pre-training, Large-Scale HPC | Flagship data-center GPUs, high VRAM, high-speed interconnects (e.g., NVLink). |
| Balanced | Fine-tuning, Private AI, Complex Inference | High-performance PCIe GPUs, balanced VRAM and compute, cost-effective scaling. |
| Cost-Optimized | Inference, Research, Development | Engineered blower-cooled RTX 5090 accelerator option for qualified deployments, budget-friendly. |
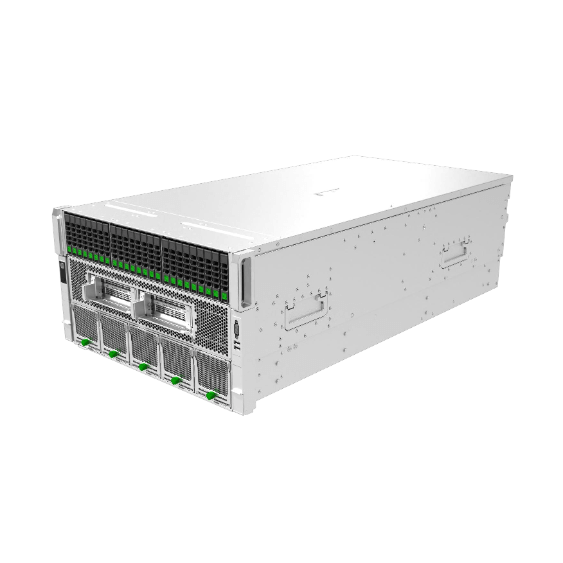
AI Servers
High-density 4U, 6U, and 10U GPU servers supporting 4 or 8 accelerators, multiple topologies, RTX 5090 options, and high-speed InfiniBand or RoCE networking for scalable AI clusters.
Why BEIJING YINTAI
- Engineering Coordination: We support requirement definition from hardware selection through cluster integration.
- Flexible Configurations: Platform, accelerator, memory, storage, networking, and cooling options are matched to the workload and budget.
- Defined Validation: Burn-in, thermal, networking, and workload tests can be specified in the project acceptance plan.
- Lifecycle Services: Ongoing maintenance and component-level repair can be scoped separately for the deployed infrastructure.
To explore advanced cooling options, learn more about our immersion-ready AI server infrastructure. For comprehensive deployment, we also offer rack-scale AI compute center integration and component-level data center GPU repair services.
Applications and Use Cases
LLM Training & Pre-training
For large-scale parameter models, we provide platforms featuring high-speed interconnects, optimizing GPU-to-GPU bandwidth.
Enterprise Fine-Tuning & Private AI
For organizations adapting open-source models to their private data, we configure servers that balance VRAM capacity with acquisition cost.
High-Throughput Inference
For production environments serving real-time AI, we deploy dense servers focused on power efficiency and high concurrent streams depending on configuration.
Computer Vision & Video Analytics
High-density GPU configurations accelerate image processing, object detection, and video analysis tasks.
Digital Twins & Rendering
Powerful compute nodes for Omniverse simulations, scientific HPC, and creative rendering farms.
Selection and Project Planning Guide
To help us design the optimal AI server solution, please provide the following information during your inquiry:
1. Target Workload: LLM training, fine-tuning, inference, or HPC?
2. Model Size: What are your VRAM requirements?
3. GPU Preference: Specific GPU architecture or model?
4. Power and Cooling: What is the power envelope and cooling capacity?
5. Networking: Do you require InfiniBand or RoCE Ethernet?
6. Timeline: Expected timeline for delivery and deployment?